Data analytics / Tableau
Book of Mormon — Authorship & Linguistic Analysis
A personal project connecting my interest in data analytics with my faith. Using 6,585 verses, I explored how word choice, vocabulary, and verse length vary across the text’s traditionally attributed authors with Python, natural language processing, and Tableau.
Interactive dashboard
Use the dashboard controls to explore the data. On smaller screens, scroll horizontally if needed. If the dashboard does not load, use “Open in Tableau” above.

Key findings
Distinct language patterns emerge across the assigned author groups, alongside shared religious themes.
- Signature words reflect subject matter. Jacob’s TF-IDF profile is dominated by the Zenos allegory: vineyard, branches, fruit, and tree. Moroni’s signature term, “jared,” reflects his abridgment of Ether.
- Vocabulary richness needs context. Enos and Jarom score highest, while Mormon contributes nearly 100,000 words. Short texts tend to score higher on vocabulary richness, so these rankings depend on sample length.
- Shared themes, distinct fingerprints. “Lord” and “God” recur across all author groups. Shared religious terms remain in thematic word clouds but are excluded from TF-IDF fingerprints to highlight more distinctive words.
- Narrative authors cluster together. Mormon and Nephi have the highest reported cosine similarity (0.686), followed by Mormon and Moroni (0.577). Jacob and Jarom are the most distinct pair (0.209).
Key Takeaway
To go beyond visual comparisons, I ran a one-way ANOVA on verse length across all primary author groups. I excluded “Various” from the book of Omni because it combines five authors with very small samples, making it unsuitable as a single author group for this comparison.
Results:
- F-statistic: 7.1096
- P-value: approximately 0.000001
If the author groups had equal mean verse lengths, the chance of observing an F-statistic this large or larger would be about 1 in 1,000,000, assuming the ANOVA assumptions hold. The differences in mean verse length are statistically significant, providing evidence beyond visual comparisons that the groups differ.
Or, in other words, if the author groups had equal mean verse lengths, a result this extreme or more extreme would occur about 1 in 1,000,000 times under the test’s assumptions.
Visualizations
Compare word use, vocabulary diversity, verse length, and similarity. Select an available chart to view the full image.
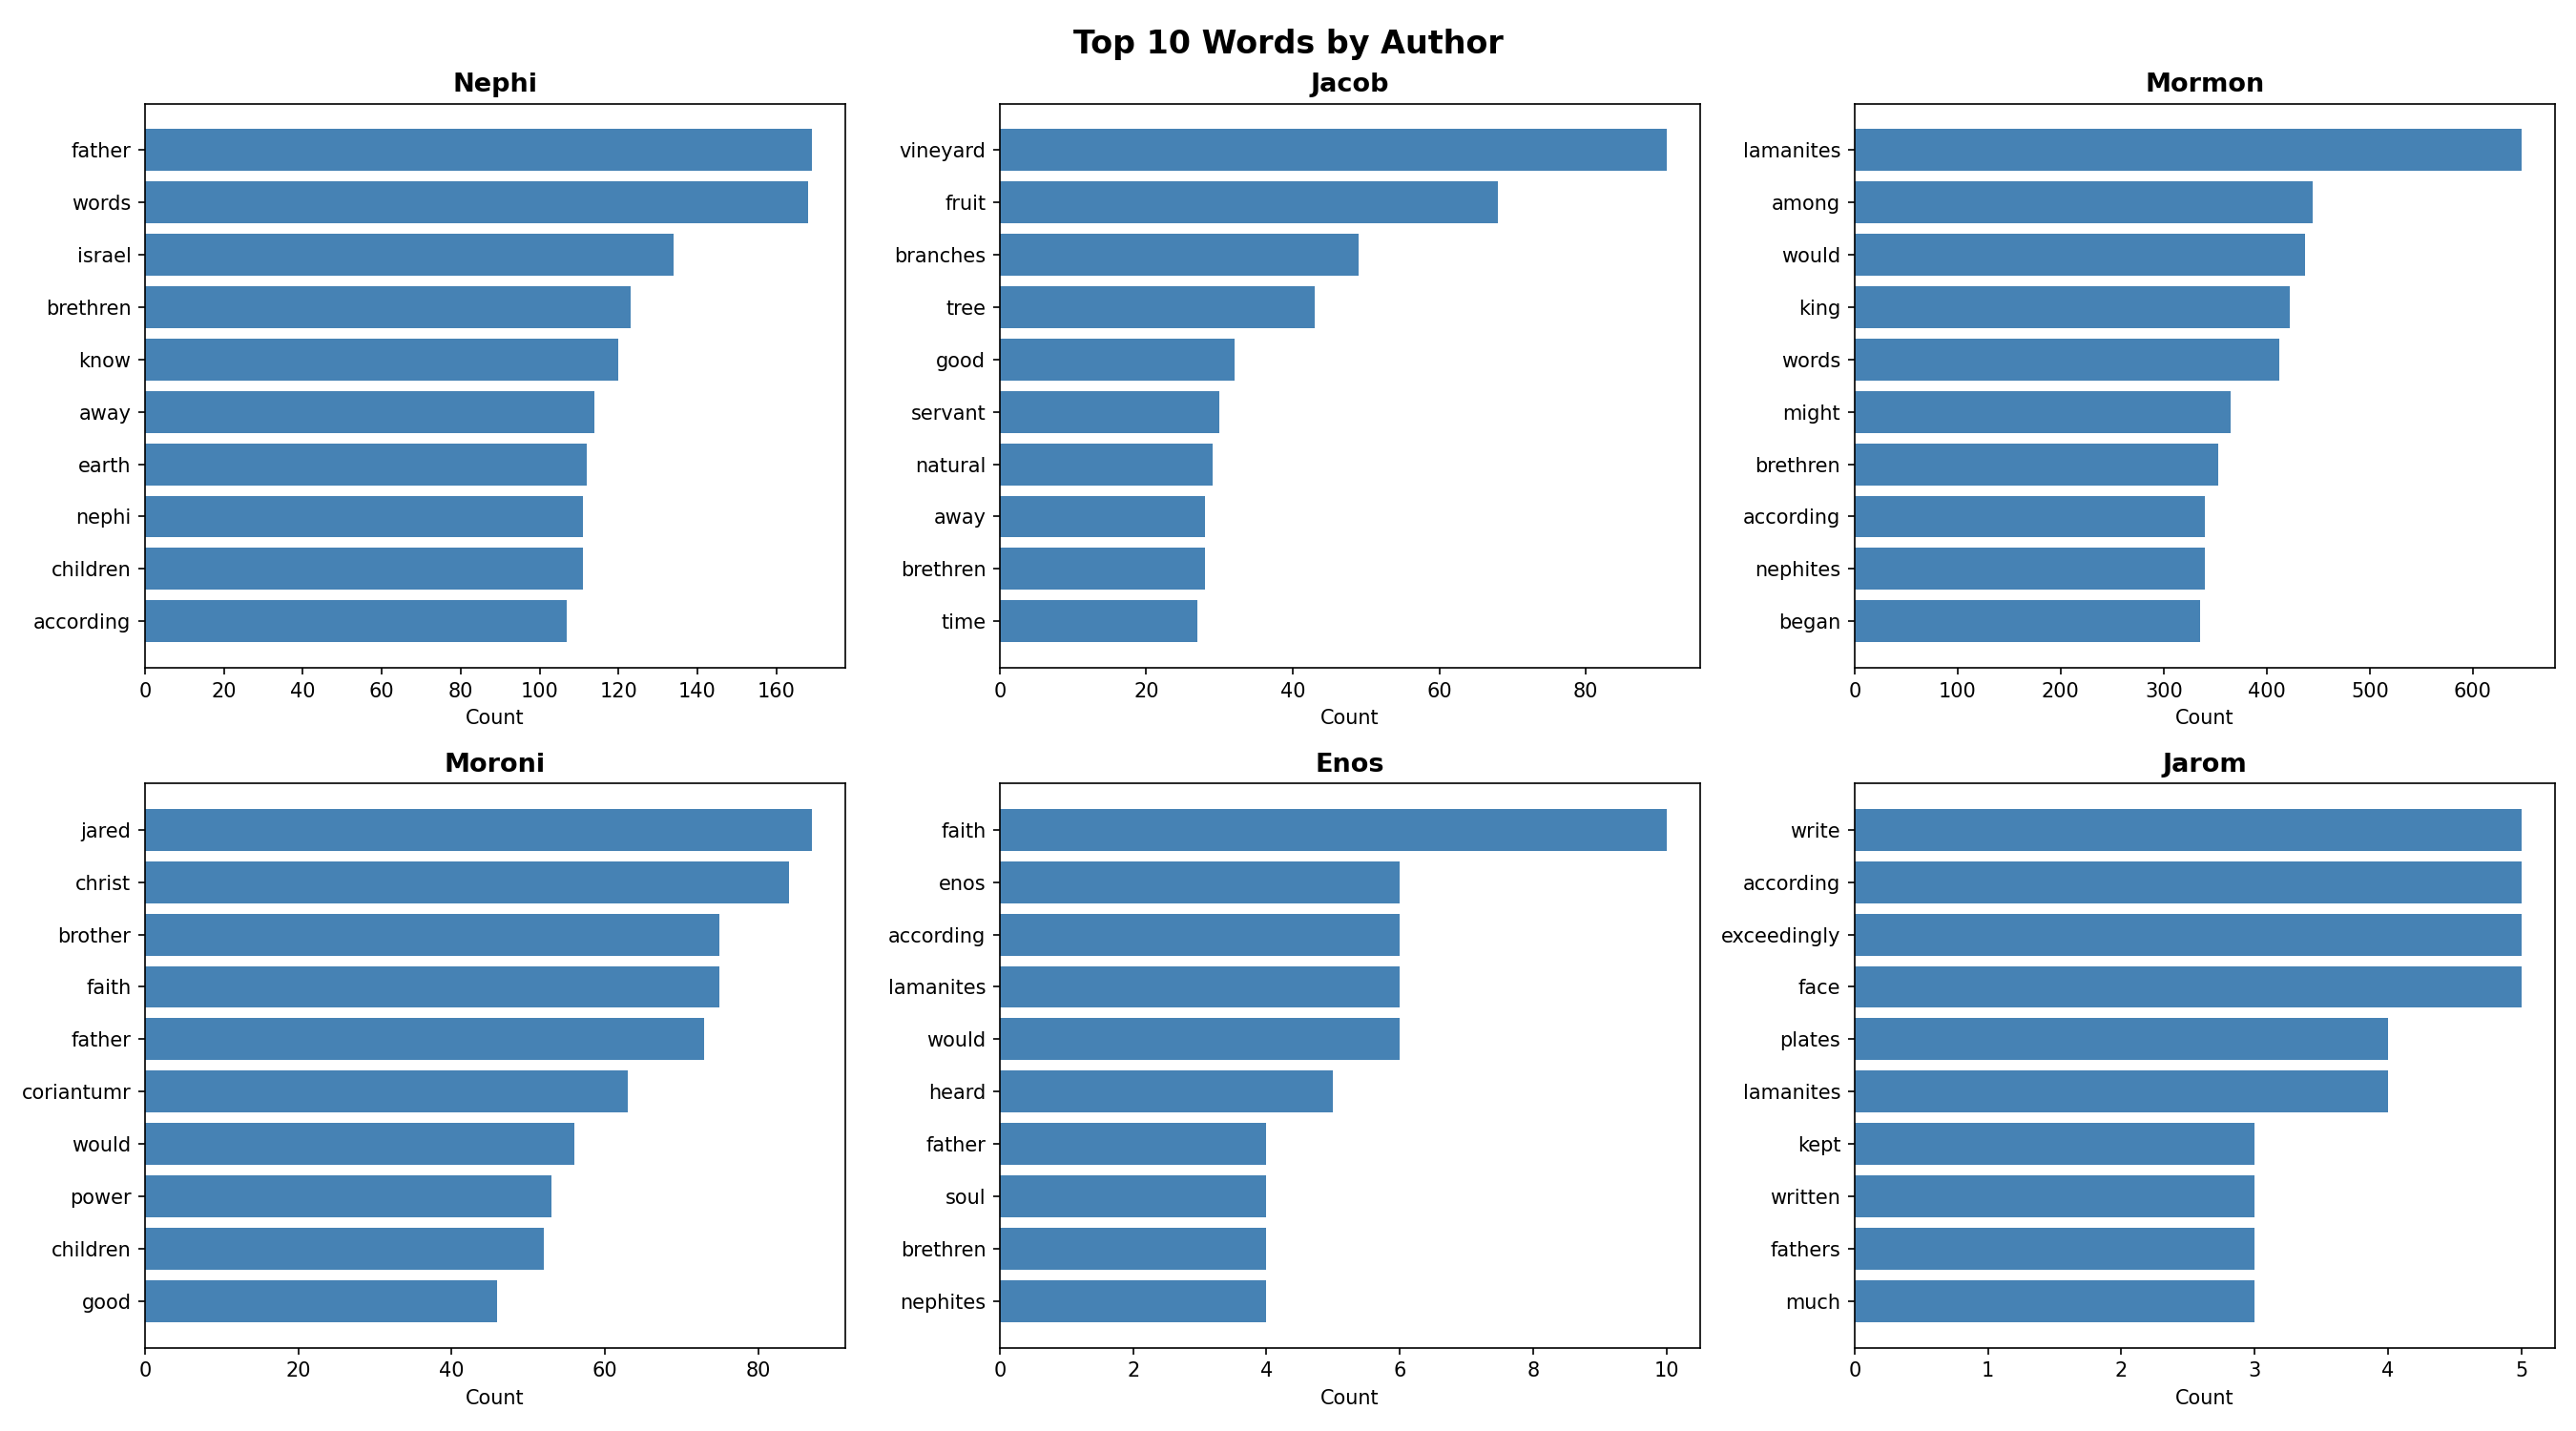
Image coming soon
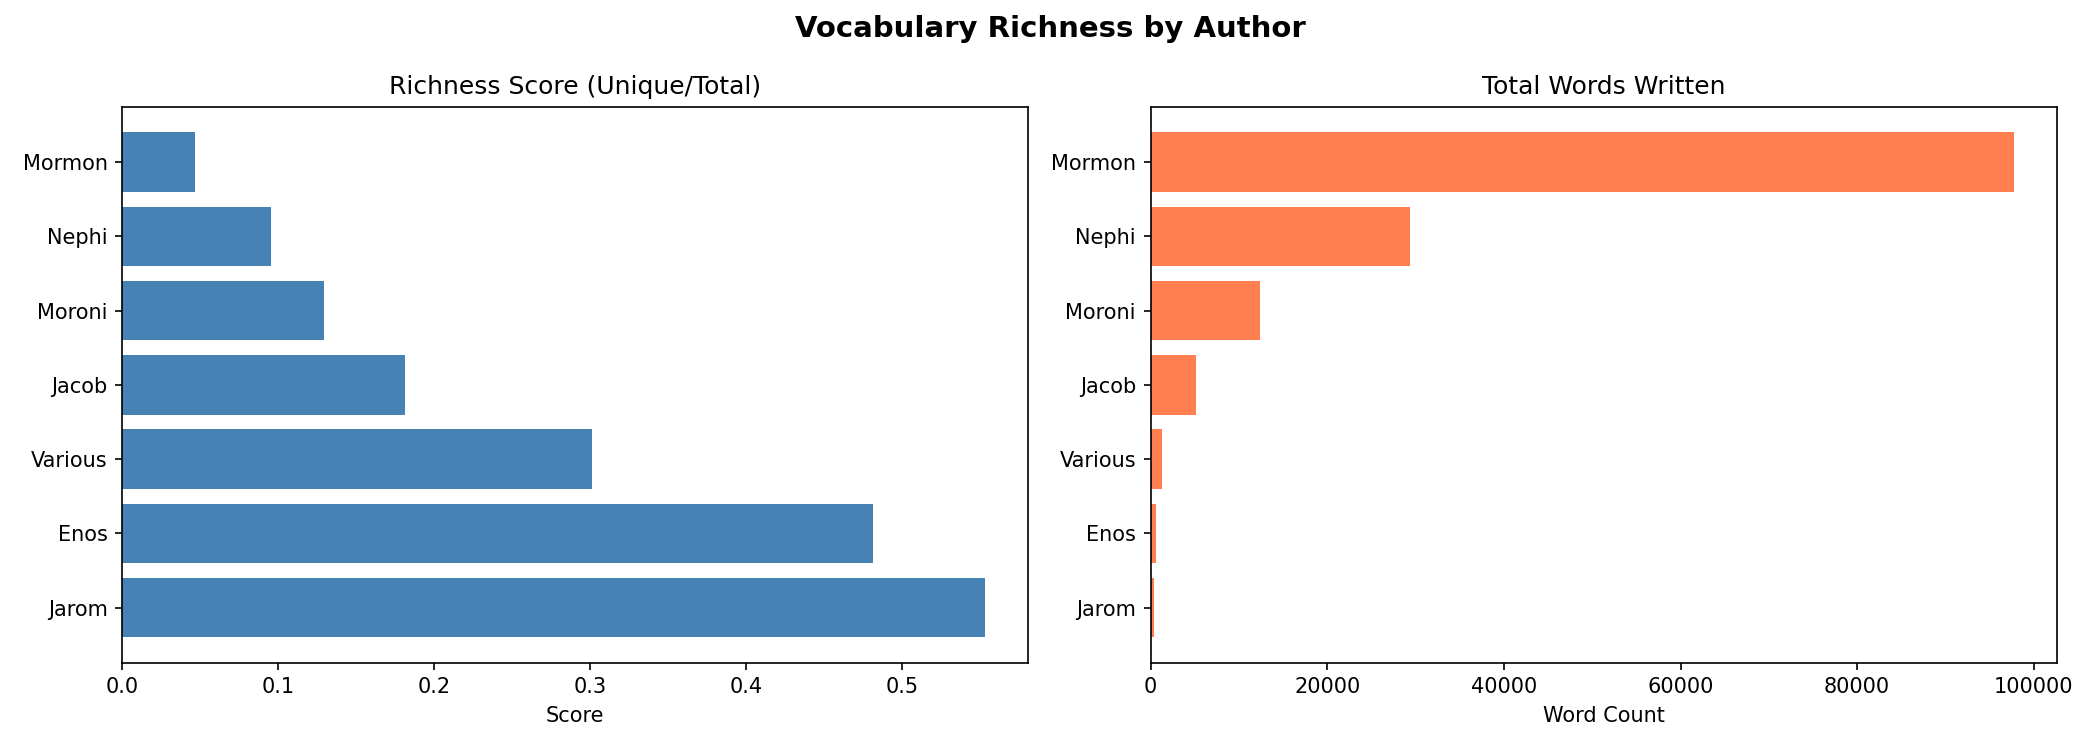
Image coming soon
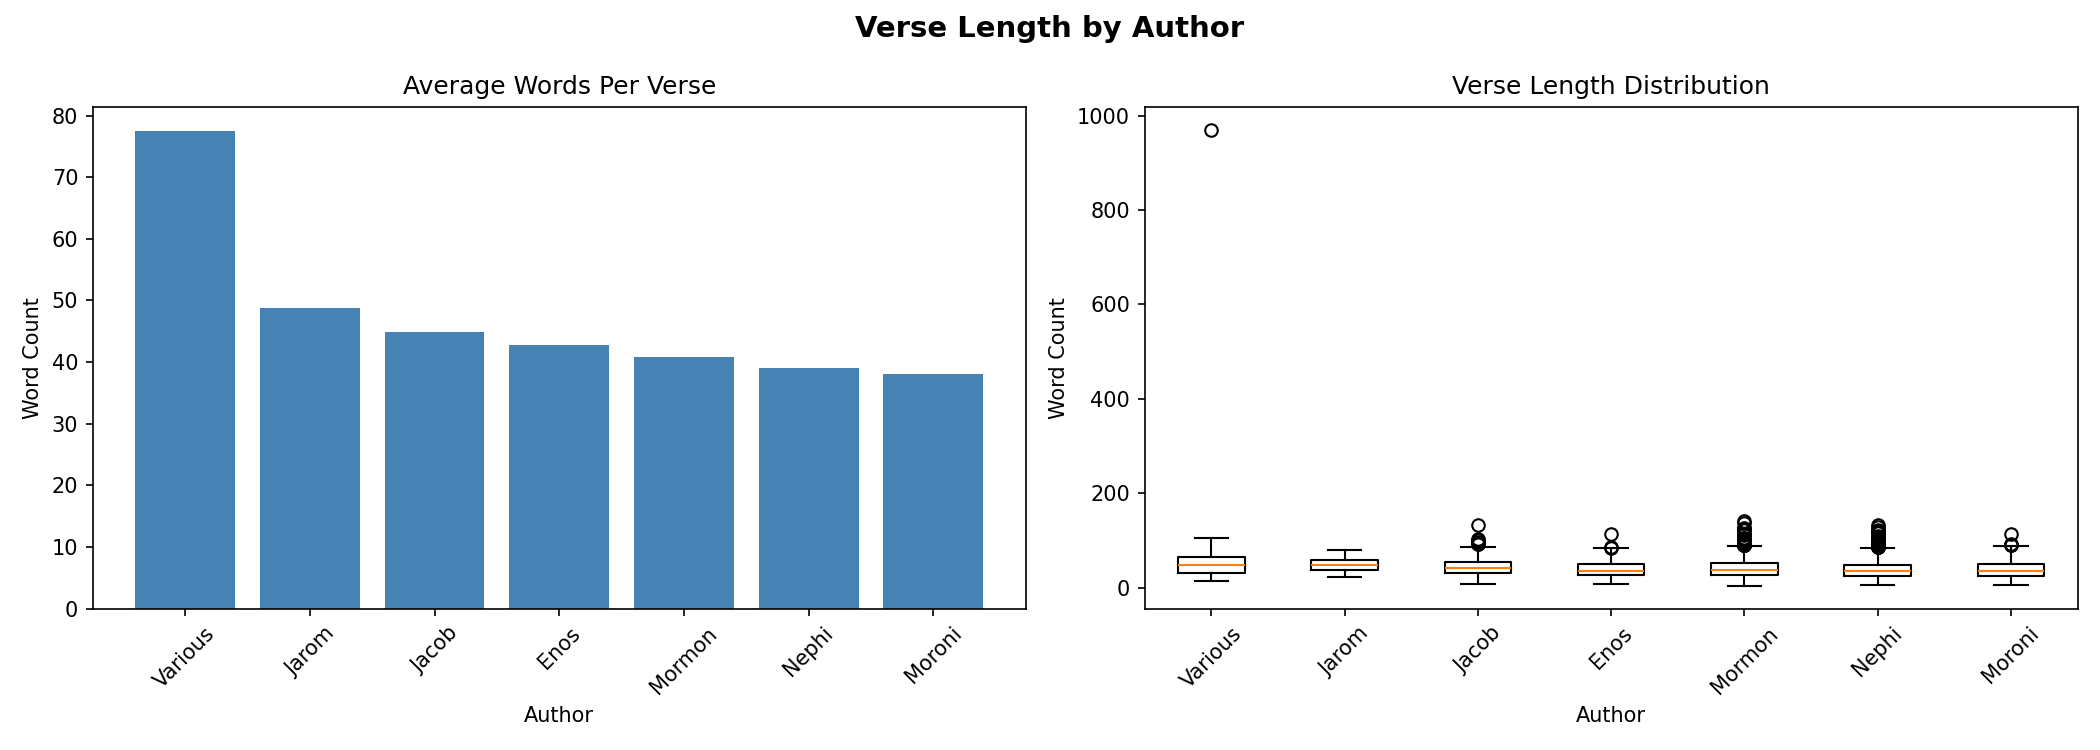
Image coming soon
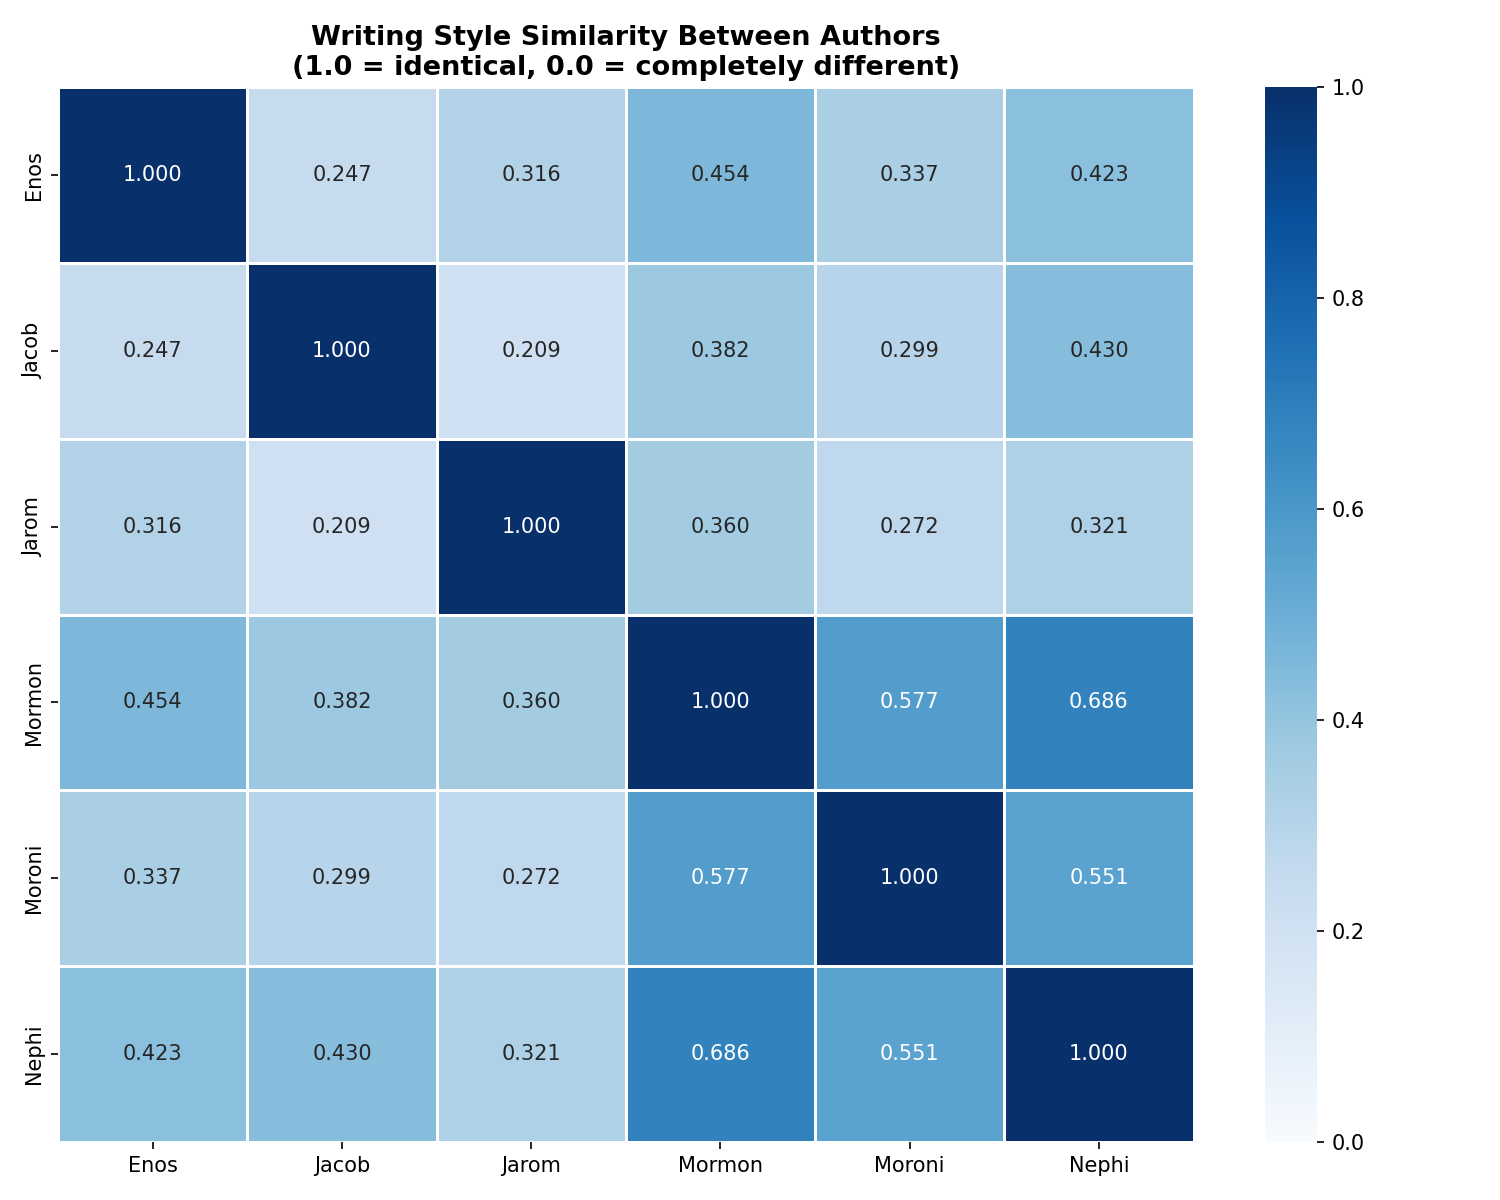
Image coming soon
Which words occur most by author?
Authorship fingerprints — word clouds
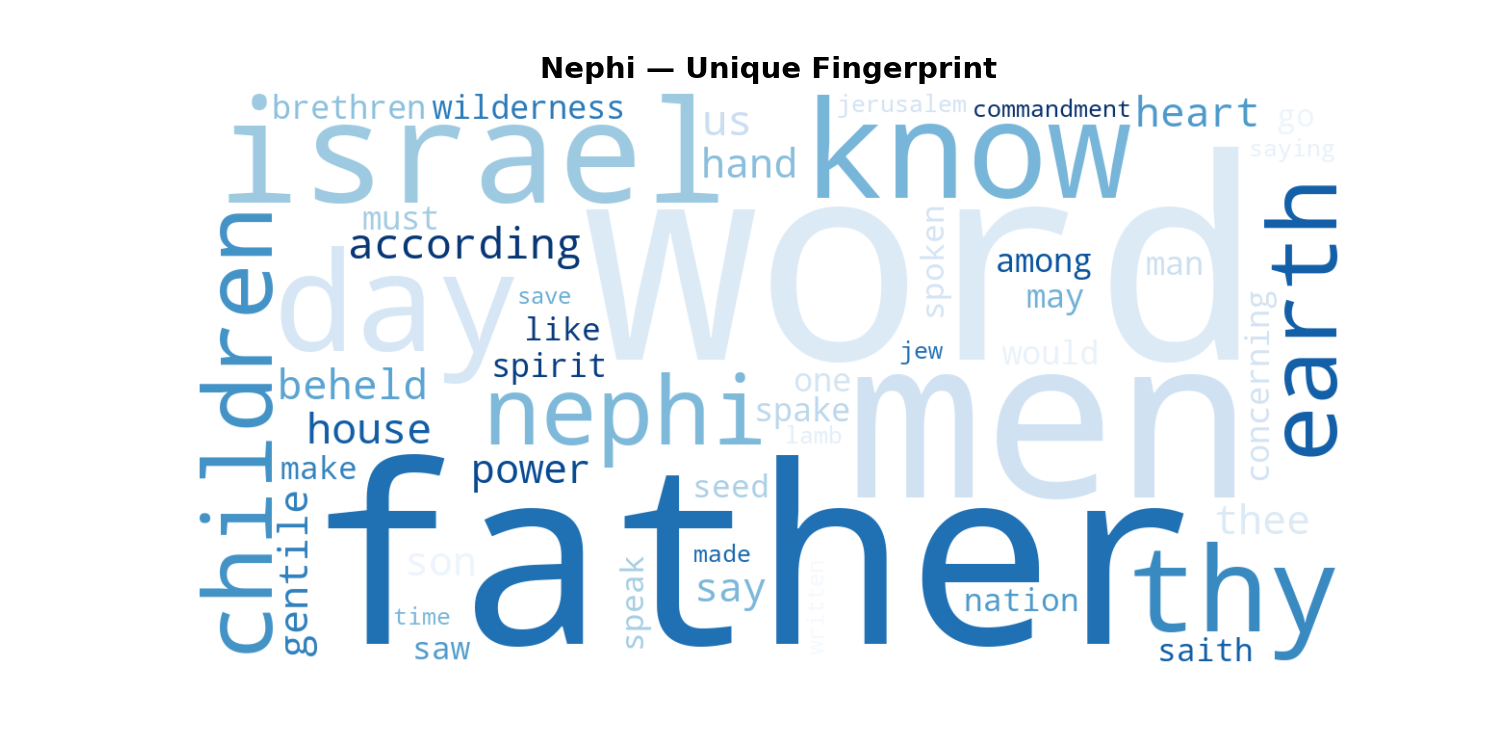
Image coming soon
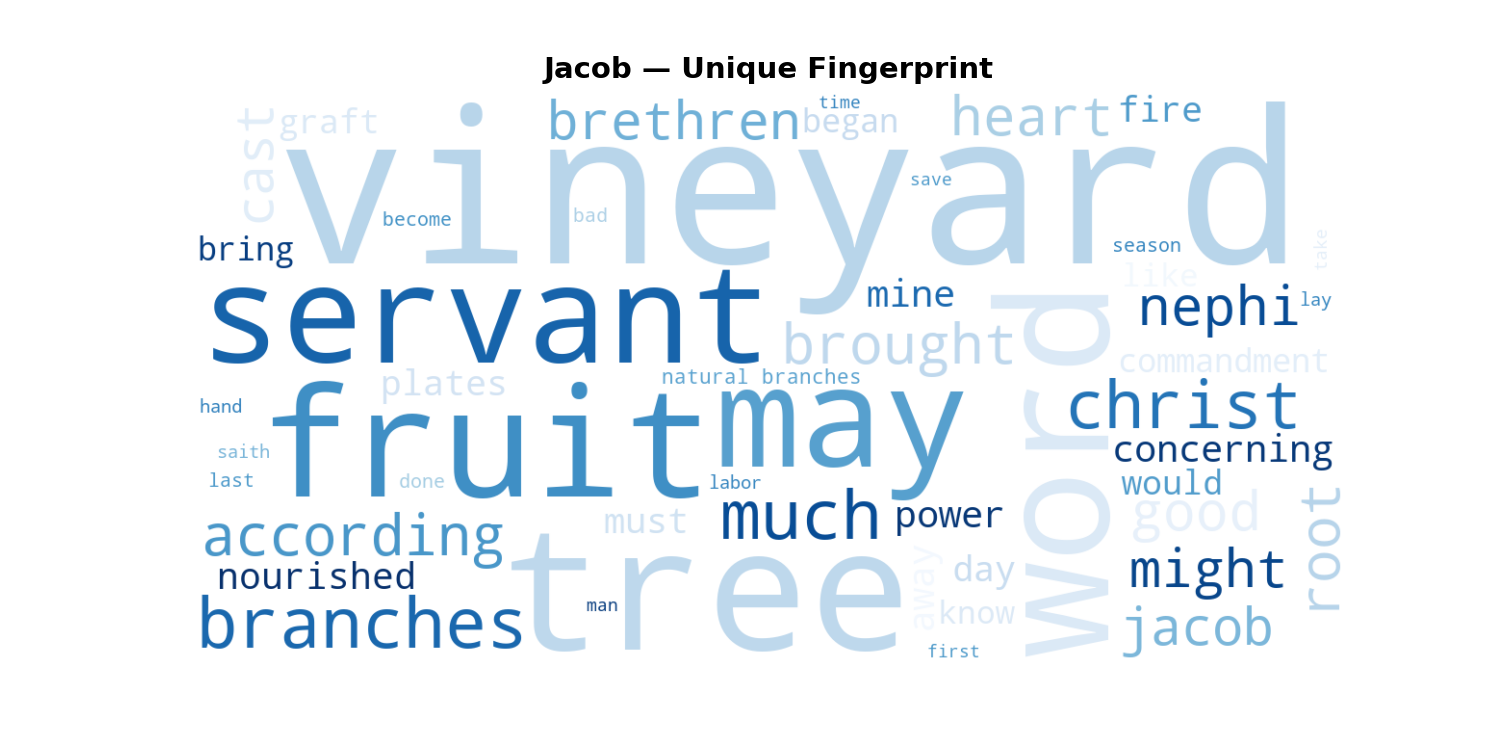
Image coming soon
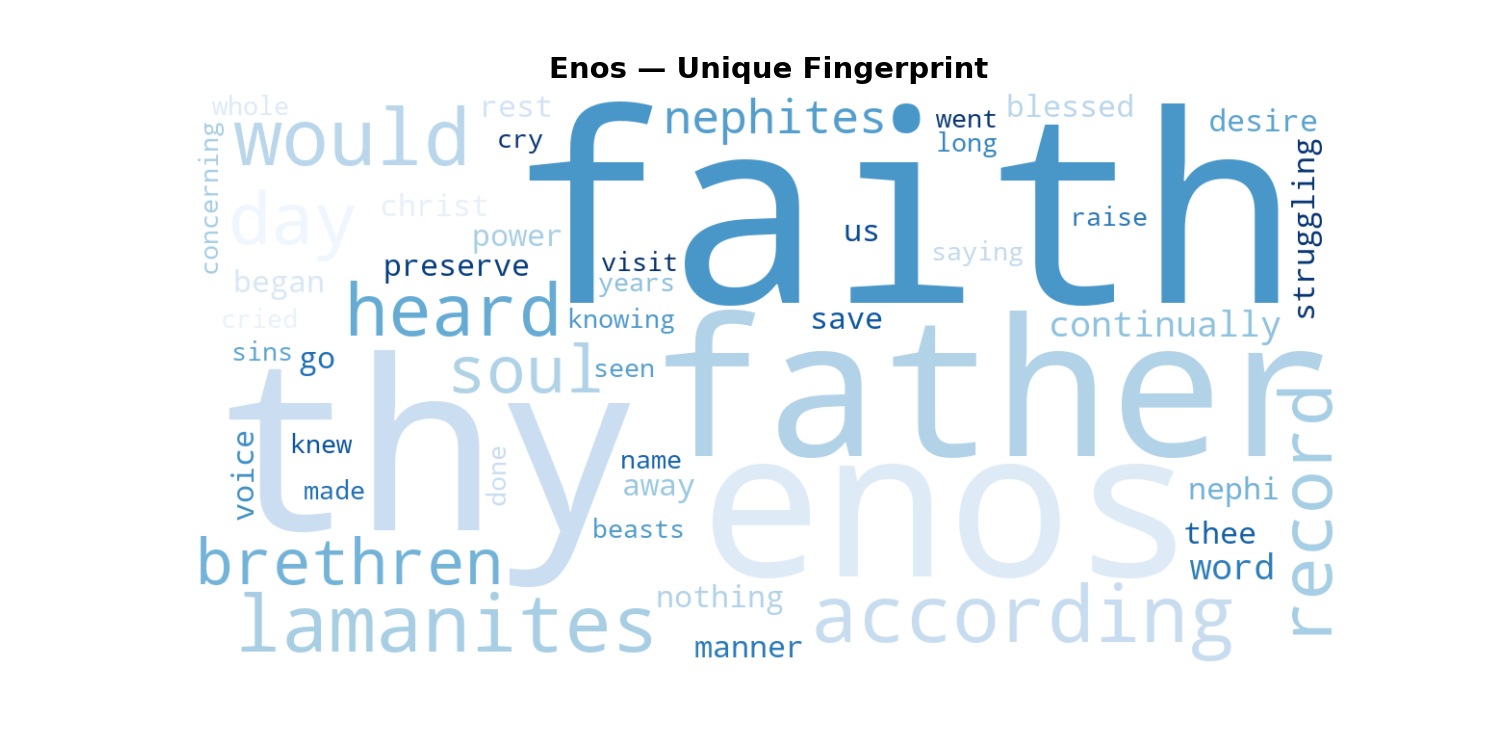
Image coming soon
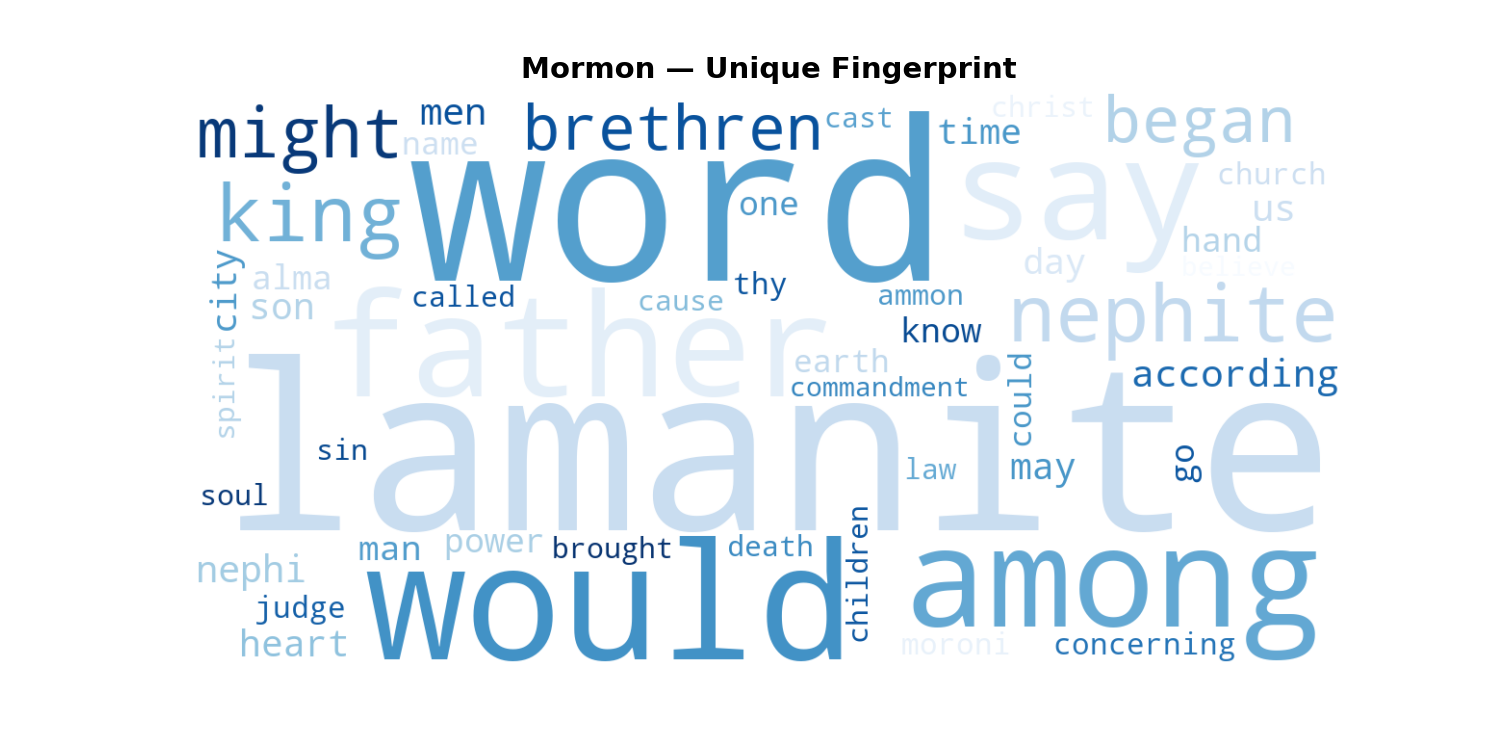
Image coming soon
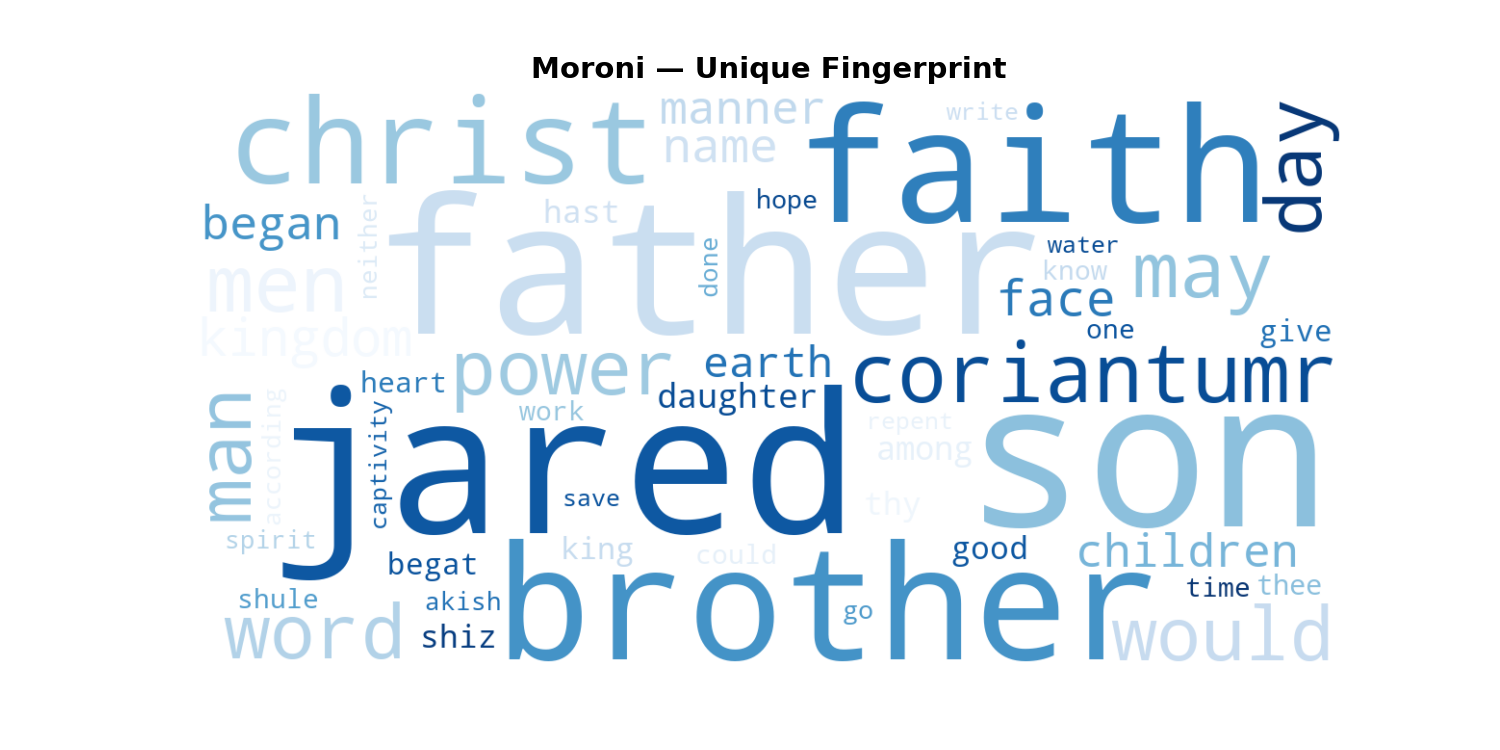
Image coming soon
Shared religious themes — word clouds
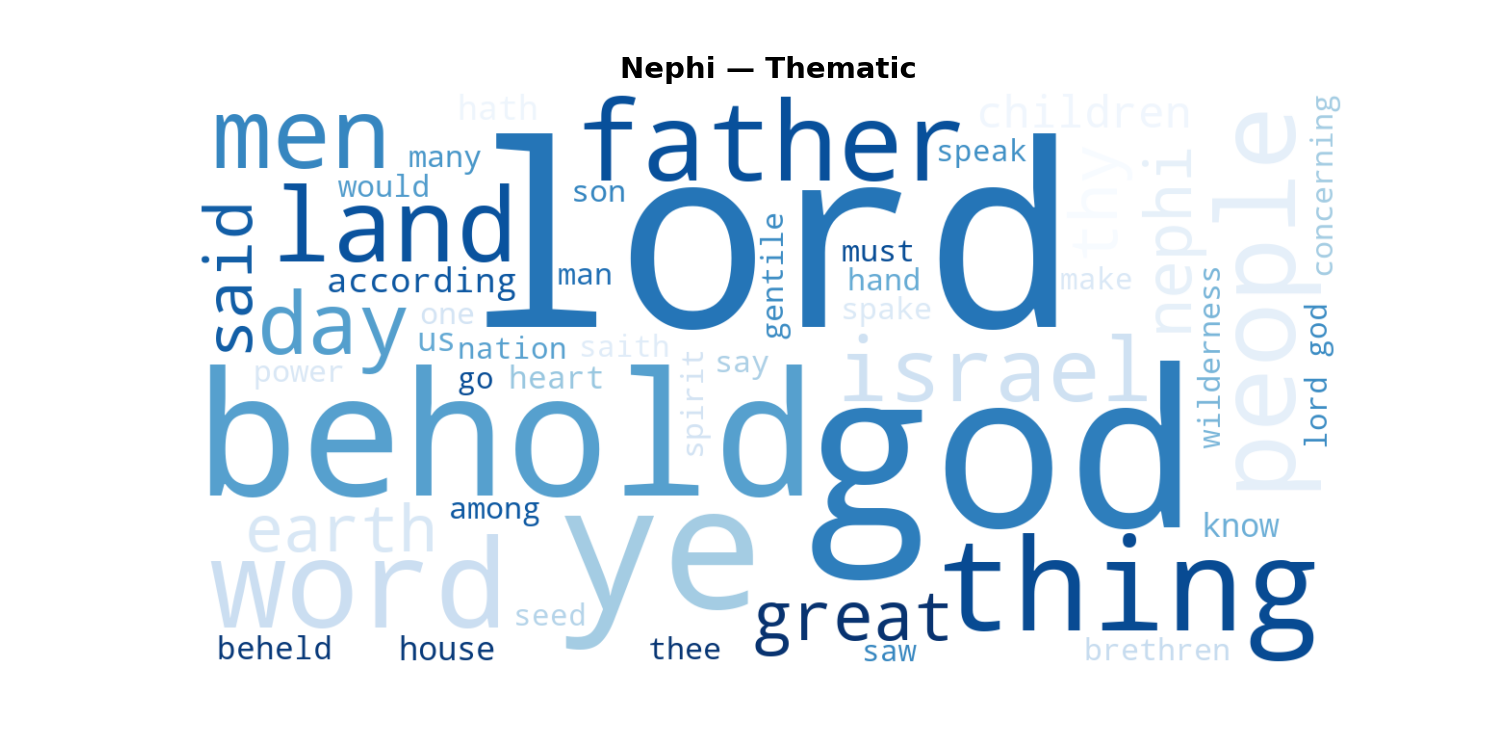
Image coming soon
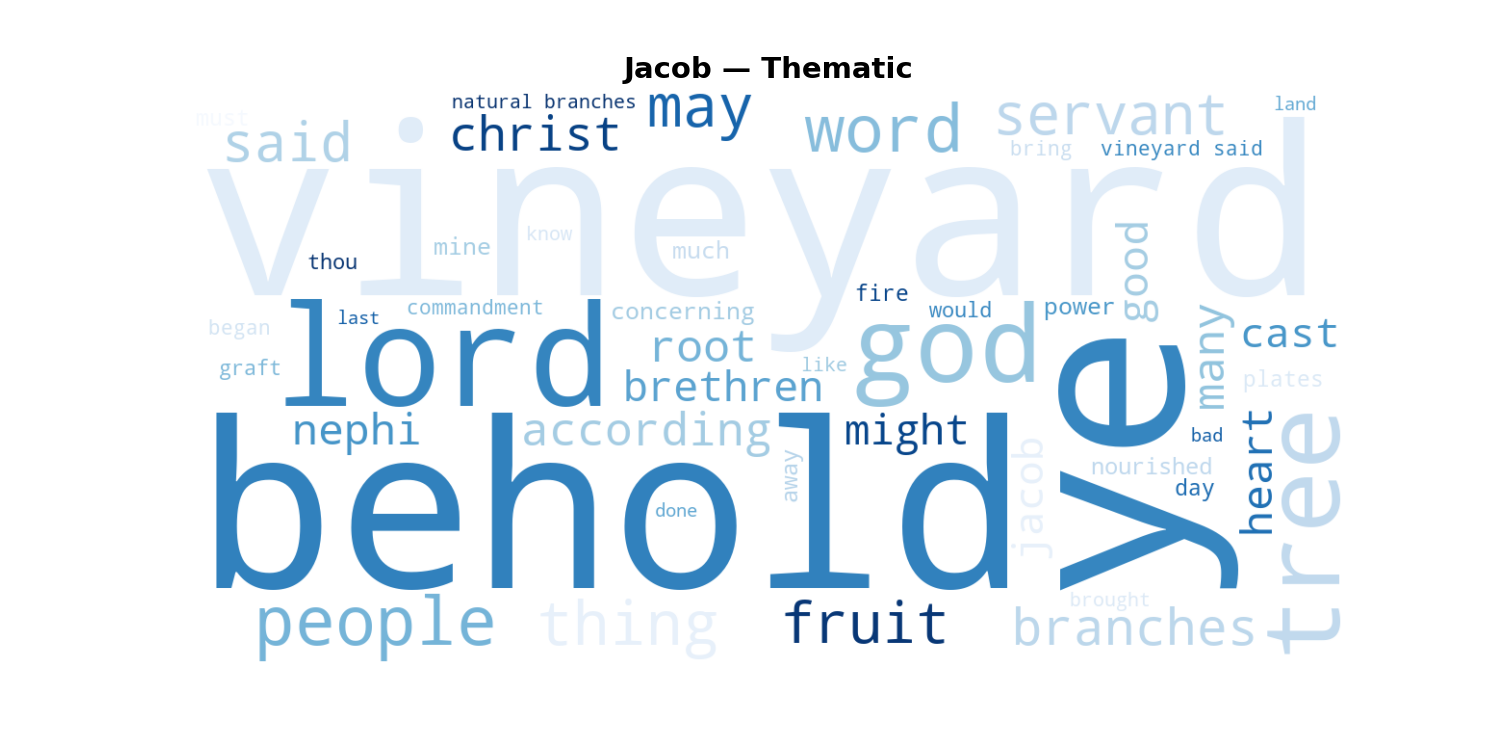
Image coming soon
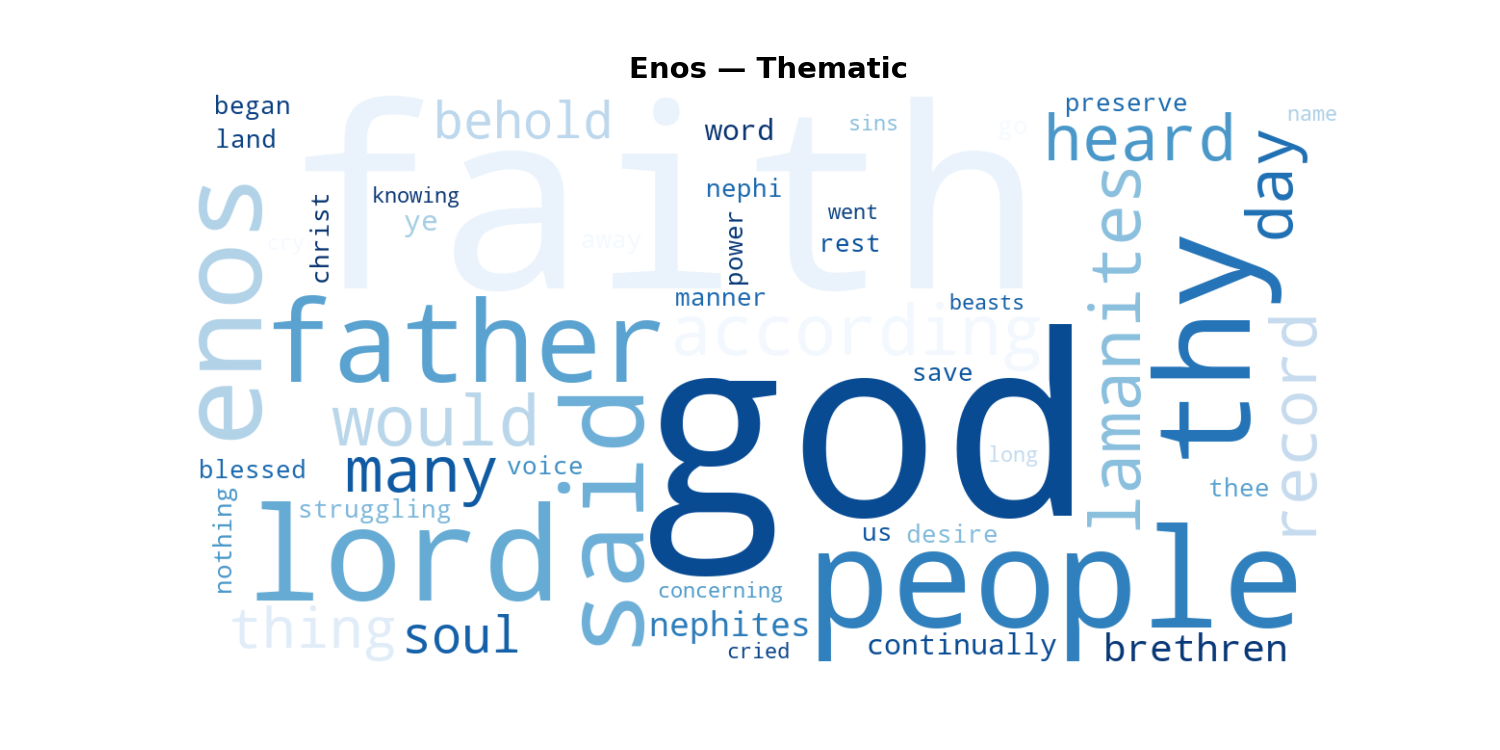
Image coming soon
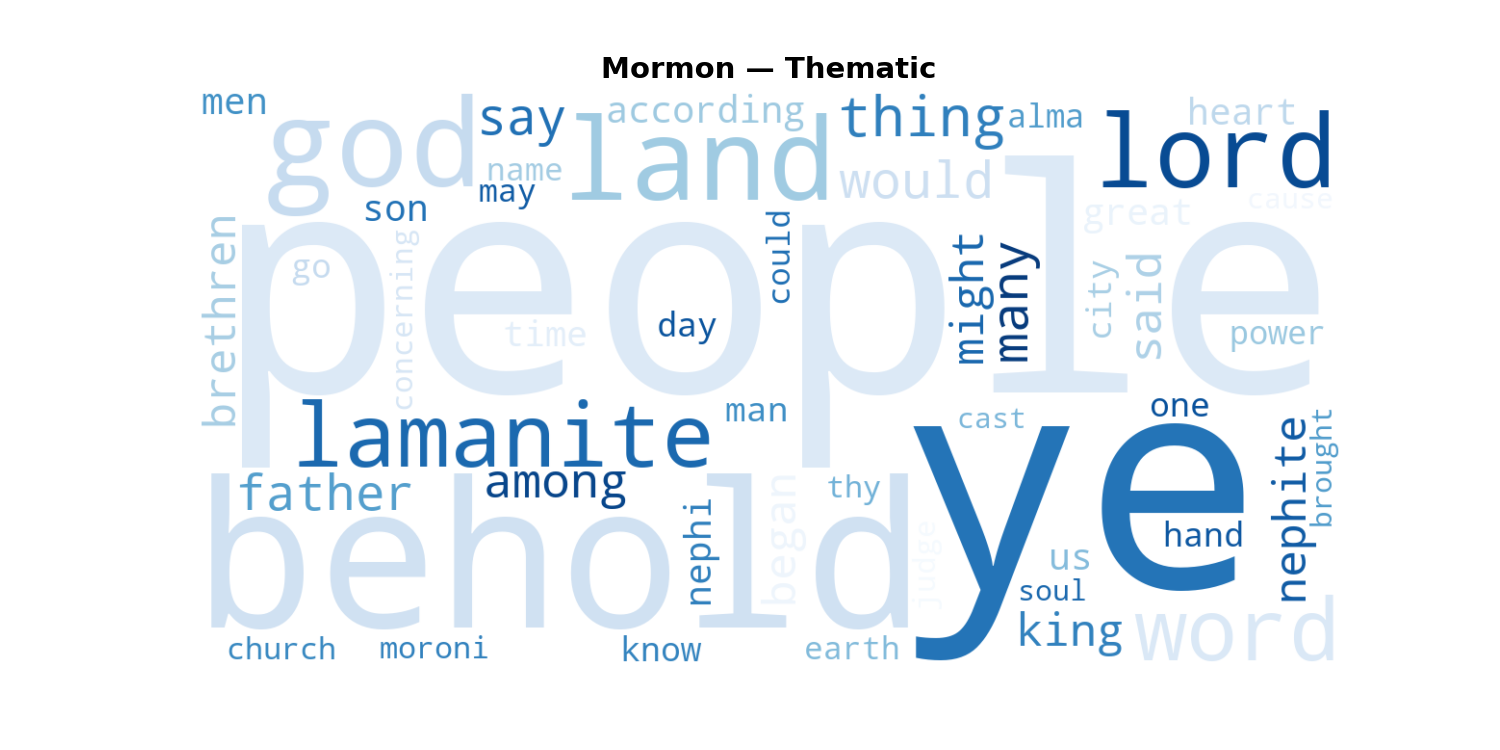
Image coming soon
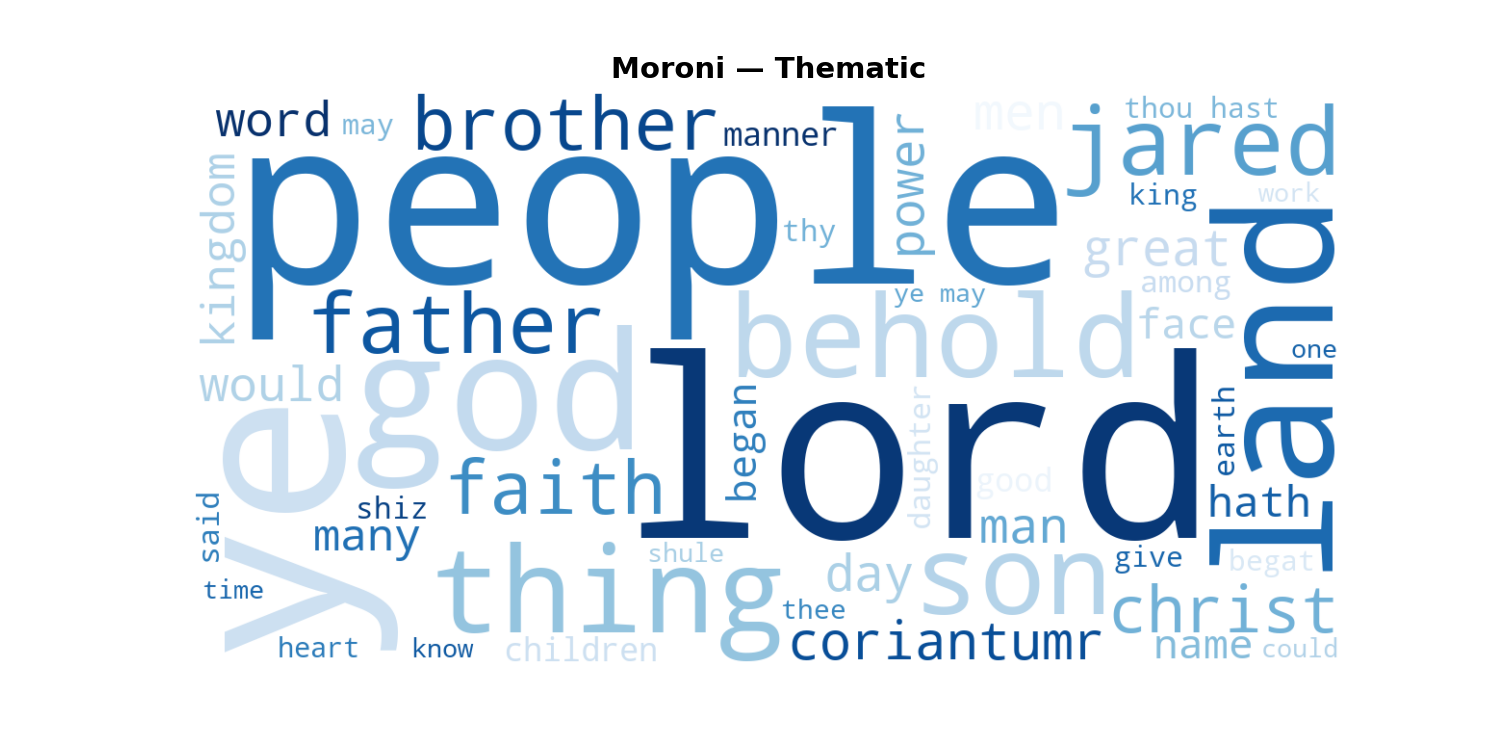
Image coming soon
Methods & interpretation
Statistical results: The project reports a one-way ANOVA on verse length (F = 7.1096, p ≈ 0.000001) and a chi-square test on word usage (χ² = 20,919.81, reported p ≈ 0). These results indicate differences across the assigned author groups under the tests’ assumptions; they do not establish authorship or explain the cause of those differences.
Scope & limitations: The dataset contains 6,585 verses, with book, chapter, verse, assigned author, word count, and text. Attribution follows the project’s traditional author and abridger assignments. The combined “Various” category in Omni was excluded from ANOVA. Text length, subject matter, and grouping decisions matter when interpreting the results.
Tools: Python, Pandas, NLTK, scikit-learn, SciPy, Matplotlib, WordCloud, and Tableau.